Search this keyword

Showing posts with label dark taxa. Show all posts

Dimly lit taxa - guest post by Bob Mesibov

The following is a first for iPhylo, a guest post by Bob Mesibov. Bob

Rod Page introduced 'dark taxa' here on iPhylo in April 2011. He wrote:

The bulk of newly added taxa in GenBank are what we might term "dark taxa", that is, taxa that aren't identified to a known species. This doesn't necessarily mean that they are species new to science, we may already have encountered these species before, they may be sitting in museum collections, and have descriptions already published. We simply don't know. As the output from DNA barcoding grows, the number of dark taxa will only increase, and macroscopic biology starts to look a lot like microbiology.

Rod suggested that 'quite a lot' of biology can be done without taxonomic names. For the dark taxa in GenBank, that might well mean doing biology without organisms – a surprising thought if you're a whole-organism biologist.

Non-taxonomists may be surprised to learn that a lot of taxonomy is also done, in fact, without taxonomic names. Not only is there a 'dark taxa' gap between putative species identified genetically and Linnaean species described by specialists, there's a 'dimly lit taxa' gap between the diversity taxonomists have already discovered, and the diversity they've named.

Dimly lit taxa range from genera and species given code names by a specialist or a group of collaborators, and listed by those codes in publications and databases, to potential type specimens once seen and long remembered by a specialist who plans to work them up in future, time and workload permitting.

In that phrase 'time and workload permitting' is a large part of the explanation for dimly lit taxa. Over the past month I created 71 species of this kind myself. Each has been code-named, diagnostically imaged, databased and placed in code-labelled bottles on museum shelves. The relevant museums have been given digital copies of the images and data.

The 71 are 'species-in-waiting'. They aren't formally named and described, but specialists like myself can refer to the images and data for identifying new specimens, building morphological and biogeographical hypotheses, and widening awareness of diversity in the group to which the 71 belong.

'Time and workload permitting'. Many of the 71 are poor-quality or fragmented museum specimens from which important morphological data, let alone sequences, cannot be obtained. Fresh specimens are needed, and fieldwork is neither quick nor easy. In my special corner of zoology, as in most such corners in zoology and botany, the widespread and abundant species are all, or nearly all, named. The unnamed rump consists of a huge diversity of geographically restricted and uncommon species. There are more than 71 in that group of mine; those are just the rare species I know about, so far.

'Time and workload permitting'. A non-taxonomist might ask, 'Why don't you just name and describe the 71 briefly, so that the names are at least available, and the gap between what's known and what's named is narrowed?' The answer is simple: inadequate descriptions are the bane of taxonomy. There are hundreds of species in my special group that were named and inadequately described long ago, and which wind up on checklists of names as 'nomen dubium' and 'incertae sedis'. Clearing up the mysteries means locating the types (which hopefully still exist) and studying them. That slow and tedious study would better have been done by the first describer.

Cybertaxonomic tools can help bring dimly lit taxa into full light, but not much. The rate-limiting steps in lighting up taxa are in the minds and lives of human taxonomists coping with the huge and bewilderingly complex diversity of life. It's not the tools used after the observing and thinking is done, it's the observing and thinking.

In their article 'Ramping up biodiversity discovery via online quantum contributions' (http://dx.doi.org/10.1016/j.tree.2011.10.010), Maddison et al. argue that the pace of naming and description can be increased if information about what I've called dimly lit taxa is publicly posted, piece by piece, 'publish as you go', on the Internet. In my case, I would upload images and data for my 71 'species-in-waiting' to suitable sites and make them freely available.

Excited by these discoveries, amateurs and professionals would rush to search for fresh specimens. Specialists would drop whatever else they were doing, borrow the existing specimens of the 71 from their repositories and do careful inventories of the morphological features I haven't documented. Aroused from their humdrum phylogenetic analyses of other organisms, molecular phylogeny labs would apply for extra funding to work on my 71 dimly lit taxa. In no time at all, a proud team of amateurs and specialists would be publishing the results of their collaboration, with 71 names and descriptions.

Shortly afterwards, flocks of pigs would slowly circle the 71 type localities, flapping their wings in unison.

Memo to Maddison et al. and other would-be reformers: the rate of taxonomic discovery and documentation is very largely constrained by the supply of taxonomists. You want more names, find more namers.

Citations, Social Media & Science

Quick note that Morgan Jackson (@BioInFocus) has written nice blog post Citations, Social Media & Science inspired by the fact that the following paper:

Kwong, S., Srivathsan, A., & Meier, R. (2012). An update on DNA barcoding: low species coverage and numerous unidentified sequences. Cladistics, no–no. doi:10.1111/j.1096-0031.2012.00408.x

cites my "Dark taxa" in the body of the text but not in the list of literature cited. This prompted some discussion of DOIs and blog posts on Twitter:


Read Morgan's post for more on this topic. While I personally would prefer to see my blog posts properly cited in papers like doi:10.1111/j.1096-0031.2012.00408.x, I suspect the authors did what they could given current conventions (blogs lack DOIs, are treated differently from papers, and many publishers cite URLs in the text, not the list of references cited). If we can provide DOIs (ideally from CrossRef so we become part of the regular citation network), suitable archiving, and — most importantly — content that people consider worthy of citation then perhaps this practice will change.

Dark taxa even darker: NCBI pulls (some) DNA barcodes from GenBank (updated)

Dark taxa have become even darker. NCBI has pulled the plug on large numbers of DNA barcode sequences that lack scientific names. For example, taxon Cyclopoida sp. BOLD:AAG9771 (tax_id 818059) now has a sparse page that has no associated sequences. From an earlier download of EMBL I know that this taxon is associated with at least 5 sequences, such as GU679674. But if you go to that sequence you get this:

Obsolete

So the the sequence is hidden. You can retrieve it by clicking on the obsolete version link, but by default it is hidden.

It's an extraordinary state of affairs that a huge slice of fundamental biodiversity data has been effectively "pulled" from view.

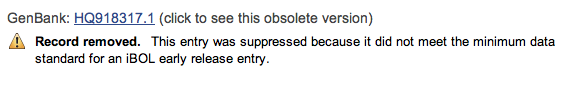
UpdateSujeevan Ratnasingham from iBOL has pointed out that the sequence I'd used above (GU679674) was not one of the ones hidden by NCBI, rather it was suppressed at the request of the investigator (which I'd have realised if I'd paid more attention to the screenshot). HQ918317 is an example of a BOLD record that was suppressed:

Hq

BLAST a sequence and get a tree and a map

I've updated the BLAST a sequence and get a tree tool described in a previous post to output additional details, such as a list of the sequences used to build the tree and some basic metadata (such as the taxon name, name of any associated host, publication, and geographic coordinates). If the sequences are geotagged, then you will also see a little map showing the localities. As ever, all this relies on SVG, so if you're browser doesn't support that out won't see much.

The example below is for the sequence EU399074, which falls in a cluster of "dark taxa"; in this case, DNA barcode sequences that haven't been properly labelled.

Blastmap

Would you give me a grant? An experiment in Open Science

I would like to know what you think of a grant proposal I plan to submit to the UK Natural Environment Research Council at the end of the month. The proposal takes the notion of "dark taxa" explored in an earlier blog post and outlines three things I'd like to do:
  1. Quantify the extent of dark taxa (taxa in GenBank that don't have scientific names)
  2. Determine how many dark taxa are genuinely new species (as opposed to taxa that are known to science but simply haven't been labelled with their proper names)
  3. Explore what we can learn about a taxon's biology even if it lacks a scientific name (e.g., the "symbiome")

Given that I discuss most of my ideas on this blog, and deposit preprints in Nature Precedings before the corresponding manuscript is published, it seems a logical extension to make grant proposals open as well. So you view the proposal on Google Docs, and you can add comments, if you wish.


Any feedback or suggestions are welcome. Do you think this is fundable? Have I made a good case for the proposed research? Is it interesting, or is it obvious, or has it already been done? Let me know what you think.

Dark taxa: GenBank in a post-taxonomic world

In an earlier post (Are names really the key to the big new biology?, I questioned Patterson et al.'s assertion in a recent TREE article (doi:10.1016/j.tree.2010.09.004) that names are key to the new biology.

In this post I'm going to revisit this idea by doing a quick analysis of how many species in GenBank have "proper" scientific names, and whether the number of named species has changed over time. My definition of "proper" name is a little loose: anything that had two words, second one starting with a lower case letter, was treated as a proper name. hence, a name like Eptesicus sp. A JLE-2010" is not a proper name, but Eptesicus andersoni is.

Mammals

Since GenBank started, every year has seen some 100-200 mammal species added to the database.


Until around 2003 almost all of these species had proper binomial names, but since then an increasing percentage of species-level taxa haven't been identified to species. In 2010 three-quarters of new tax_ids for mammals weren't identified.

Invertebrates

For "invertebrates" 2010 saw an explosive growth in the number of new taxa sequenced, with nearly 71,000 new taxa added to GenBank.


This coincides with a spectacular drop in the number of properly-named taxa, but even before 2010 the proportion of named invertebrate species in GenBank was in decline: in 2009 just over a half of the species added had binomials.

Bacteria

To put this in perspective, here are the equivalent graphs for bacteria.
Although at the outset most of the bacteria in GenBank had binomial names, pretty quickly the bulk of sequenced bacteria had informal names. In 2010 less than 1% of newly sequenced bacteria had been formerly described.

Dark taxa

For bacteria the graphs are hardly surprising. To get a proper name a bacterium must be cultured, and the vast majority of bacteria haven't been (or can't be) cultured. Hence, microbiologists can gloat at the nomenclatural mess plant and animal taxonomists have to deal with only because microbiologists have a tiny number of names to deal with.

For mammals and invertebrates there's clear a decline in the use of proper names.It would be tempting to suggest that this reflects a decline in the number of taxonomists - there might simply not be enough of them in enough groups to be able to identify and/or describe the taxa being sequenced.

However, if we look at the recent peaks of unnamed animal species, we discover that many have names like Lepidoptera sp. BOLD:AAD7075, indicating that they are DNA Barcodes from the Barcode of Life Data Systems. Of the 62,365 unnamed invertebrates added last year, 54,546 are BOLD sequences that haven't been assigned to a known species. Of the 277 unnamed mammals, 218 are BOLD taxa. Hence, DNA bnacording is flooding Genbank with taxa that lack proper names (and typically are represented by a single DNA bnacode sequence).

There are various ways to interpret these graphs, but for me the message is clear. The bulk of newly added taxa in GenBank are what we might term "dark taxa", that is, taxa that aren't identified to a known species. This doesn't necessarily mean that they are species new to science, we may already have encountered these species before, they may be sitting in museum collections, and have descriptions already published. We simply don't know. As the output from DNA barcoding grows, the number of dark taxa will only increase, and macroscopic biology starts to look a lot like microbiology.


A post-taxonomic world
If we look at the graphs for bacteria, we see that taxonomic names are virtually irrelevant, and yet microbiology seems to be doing fine as a discipline. So, perhaps it's time to think about a post-taxonomic world where taxonomic names, contra Patterson et al., are not that important. We can discover a good deal about organismal biology from GenBank alone (see my post Visualising the symbiome: hosts, parasites, and the Tree of Life for some examples, as well as Rougerie et al. 2010 doi:10.1111/j.1365-294X.2010.04918.x).

This leaves us with two questions:
  1. How much biology can we do without taxonomic names?
  2. If the lack of taxonomic names limits what we can do (and, playing devil's advocate, this is an open question) how can we speed up linking GenBank sequences to names?


I suspect that the answer to (1) is "quite a lot" (especially if we think like microbiologists). Question (2) is ultimately a question about how fast we can link literature, museum collections, sequences, and phylogenies. If progress to date is any indication, we need to rethink how we do this, and in a hurry, because dark taxa are accumulating at an accelerating rate.

How the analyses were done

Although the NCBI makes a dump of its taxonomic database available via FTP (at ftp://ftp.ncbi.nih.gov/pub/taxonomy/), this dump doesn't have dates for when the taxa were added to the database. However, using the Entrez EUtilities we can get the tax_ids that were published within a given date range. For example, to retrieve all the tax_ids added to the database in December 2010, we set the URL parameters &mindate=2010/12/01 and &maxdate=2010-12-31 to form this URL:

http://eutils.ncbi.nlm.nih.gov/entrez/eutils/esearch.fcgi?db=taxonomy&mindate=2010/12/01&maxdate=2010/12/31&retmax=1000000.

I've set &retmax to a big number to ensure I get all the tax_ids for that month (in this case 23511). I then made a local copy of the NCBI database in MySQL ( instructions here) and queried for all species-level taxa in GenBank. I used a rather crude regular expression REGEXP '^[A-Z][a-z]+ [a-z][a-z]+$' to find just those species names that were likely to be proper scientific names (i.e., no "sp.", "aff.", museum or voucher codes, etc.). To group the species into major taxonomic groups I used the division_id.

Results are available in a Google Spreadsheet.